Analyzing Jev Outcomes with Validator
/ 2 min read
Table of Contents
Find the errors. Measure what changes.
System 1 decision models like Jev run inside a workflow. Think of them as cognitive cogs in a deterministic machine of source code. How do we know where and when these decision model outputs are wrong, and how can we improve them?
I built Validator for that job. It is a CLI that compares reviewed expected labels with saved classifier outcomes. It works with single-label and multi-label classifiers, including Jev workflows.
- Bring your data. Pair expected labels with your workflow’s saved predictions.
- Find the mistakes. See missed labels, extra flags, and the cases behind them.
- Measure what changes. Compare runs after adjusting the workflow.
Worked example: Evaluating a code-review workflow
87.1% micro-F1. Half the security findings missed. These 20 synthetic reviews show how Validator exposes a weakness behind the average.
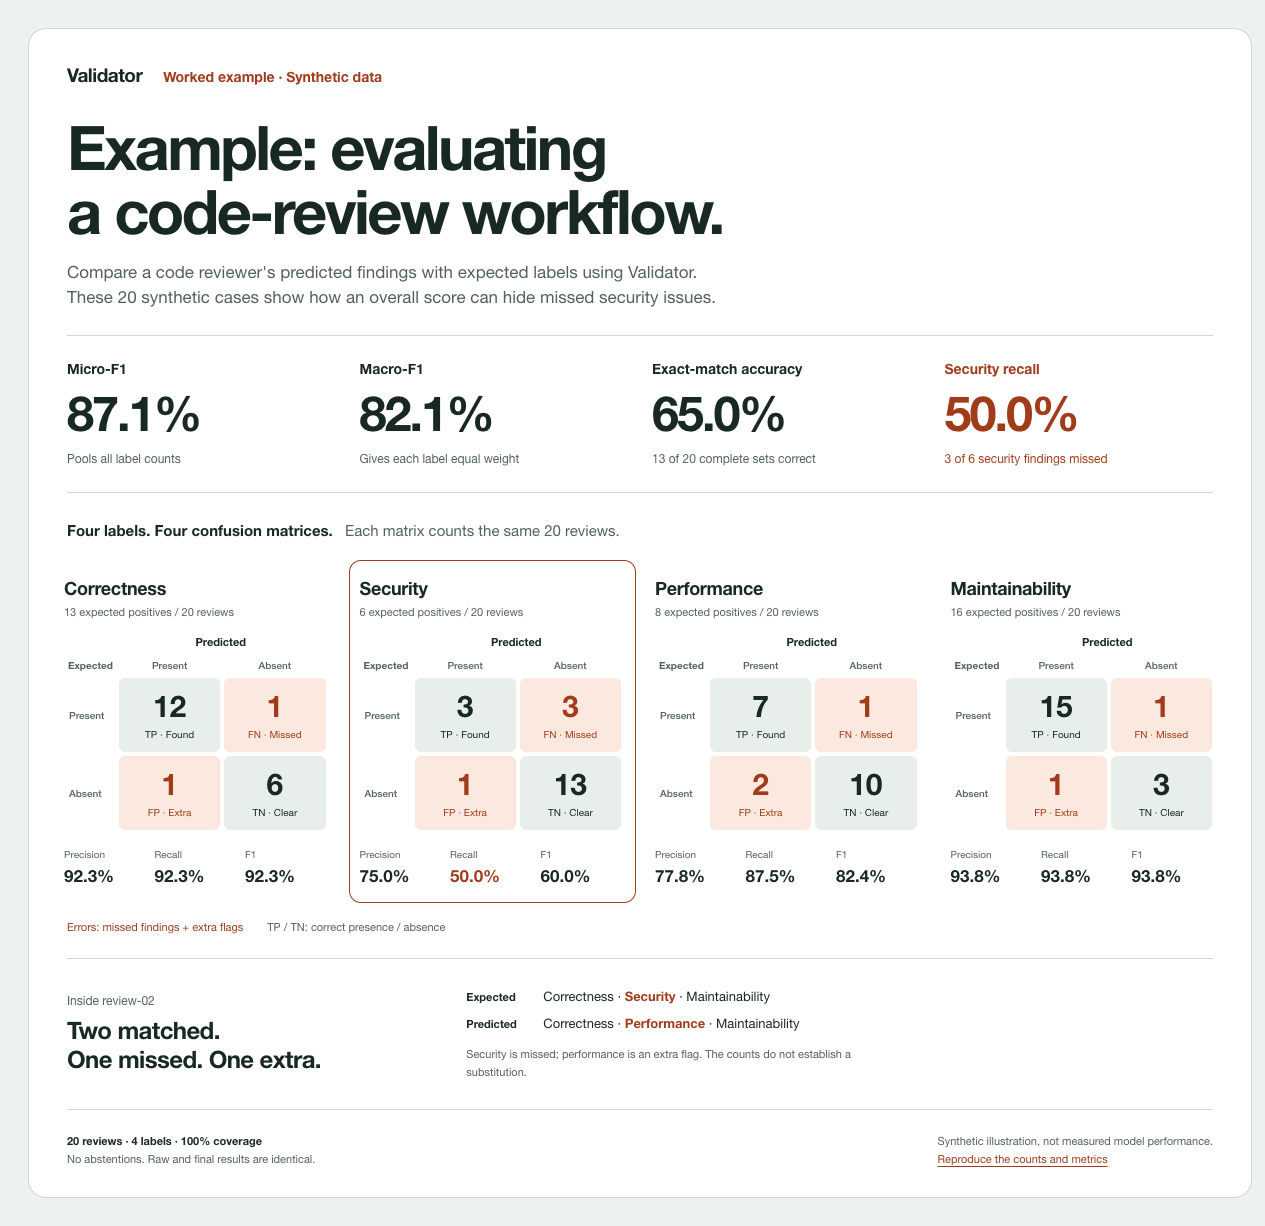
Synthetic example, not measured Jev performance. Figure based on Validator’s JSON results.
Command-line interface
Run your classifier, save its predictions, and evaluate them against your reviewed labels:
validator evaluate \ --dataset data/golden.json \ --predictions data/predictions.json \ --config validator.json \ --out runs/currentAfter a change, compare the saved reports:
validator compare \ runs/baseline/report.json \ runs/current/report.jsonSee the Validator README for the input formats and full example.